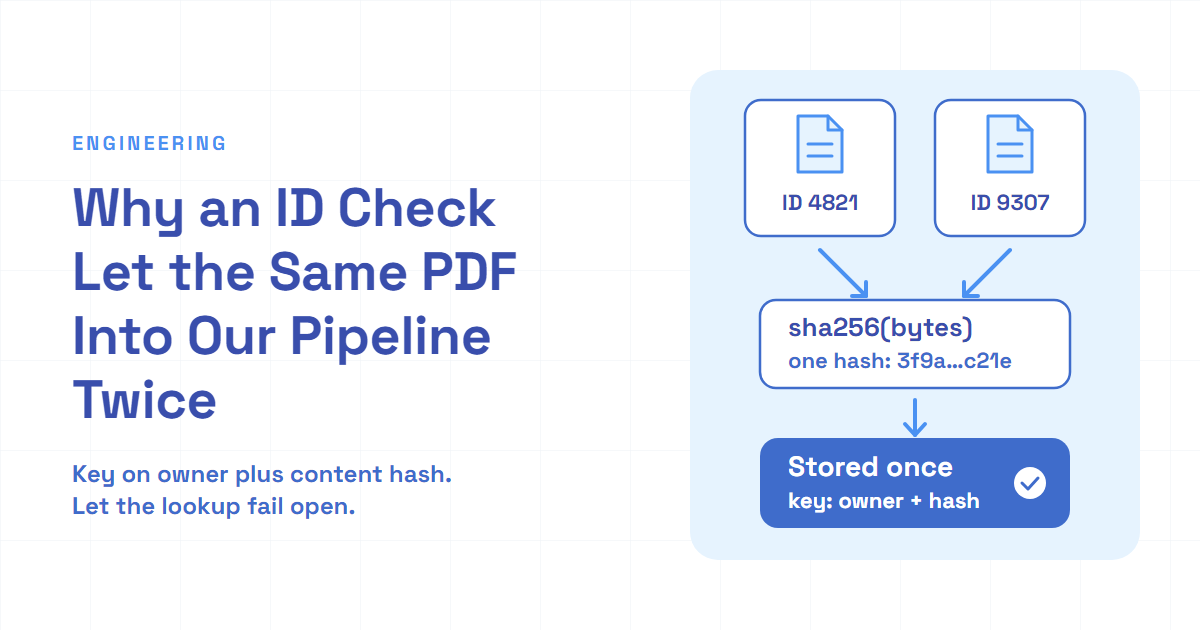
Why an ID Check Let the Same PDF Into Our Pipeline Twice
The same PDF reached our pipeline twice under new IDs. Here's how to deduplicate documents by content hash, key it by owner and let the lookup fail open.
 Utkarsh Gupta





IRIS
Multibagg AI is an AI powered stock research and analysis platform. We provide data, information, content, and analytics for publicly traded Indian companies listed on NSE and BSE. AI can make mistakes, check important information.
Prices might be delayed by a few minutes.
Join our Exclusive Community


Join our Exclusive Community
Made with 💙 in India. © Finsky Technologies Pvt Ltd. 2026


Notes from the engineers building AI-powered stock research for Indian investors.
10 posts
The same PDF reached our pipeline twice under new IDs. Here's how to deduplicate documents by content hash, key it by owner and let the lookup fail open.
Utkarsh GuptaA Qdrant filter timeout at 60 seconds, yet one query took 0.86 ms. How an integer match on a keyword payload index forced a full scan, and the simple fix.
Utkarsh Gupta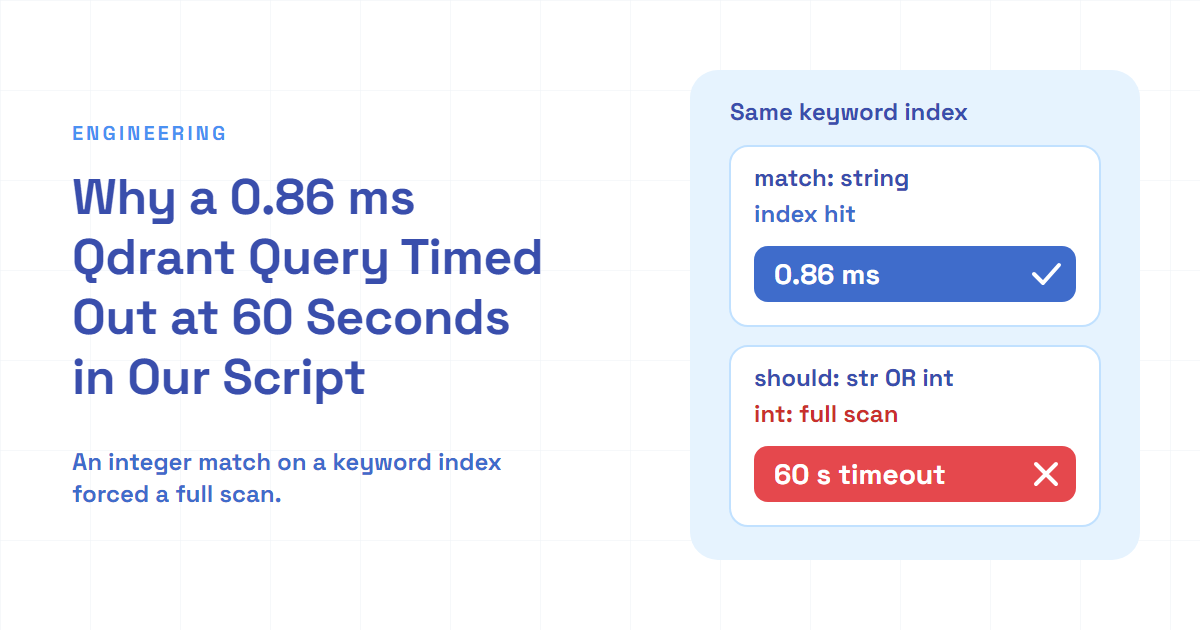
You can't catch a segfault in Python. How we moved PDF conversion into a spawned child process, so a native OCR crash fails one document, not the worker.
Utkarsh Gupta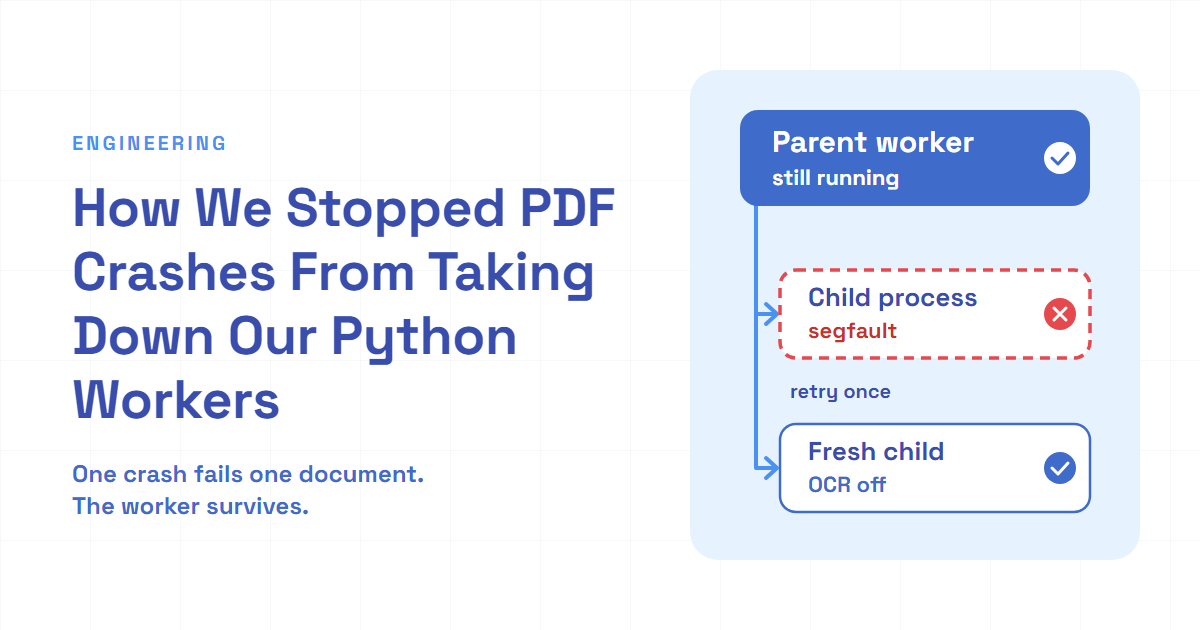
Batch LLM report generation with zero failures, yet a prompt tuned on one industry gave all 201 reports an EV section. How we caught it and what fixed it.
Utkarsh Gupta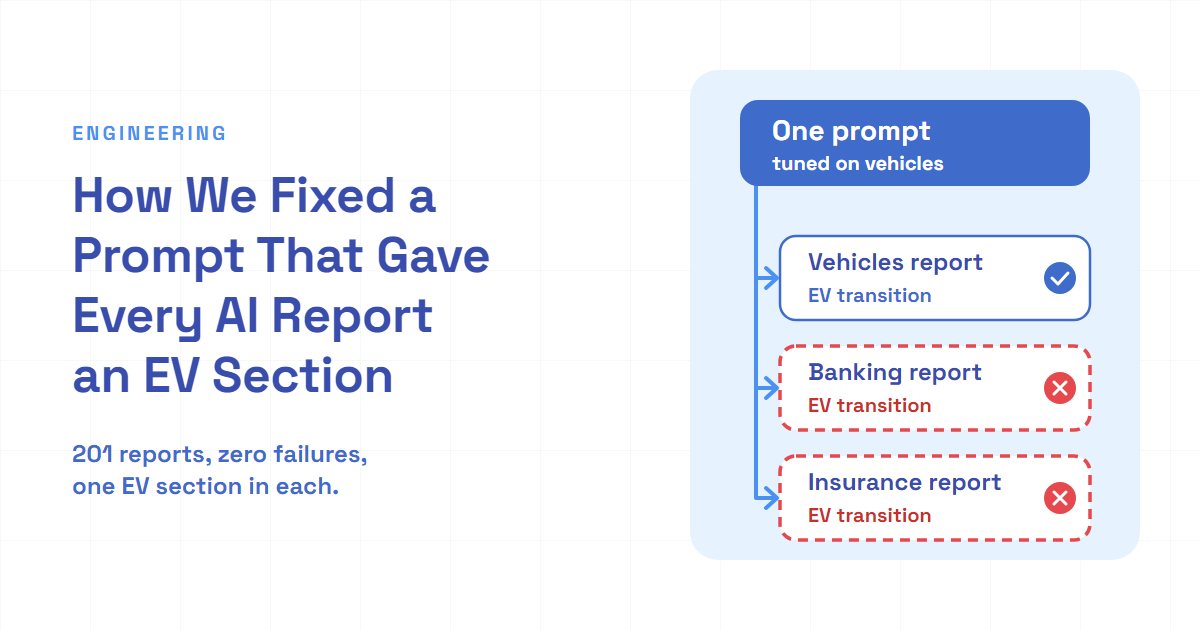
Our eval accuracy drop to 50% wasn't the model. Half the golden set pointed at retired IDs. How we remapped 1,009 items by content hash and fixed the labels.
Utkarsh Gupta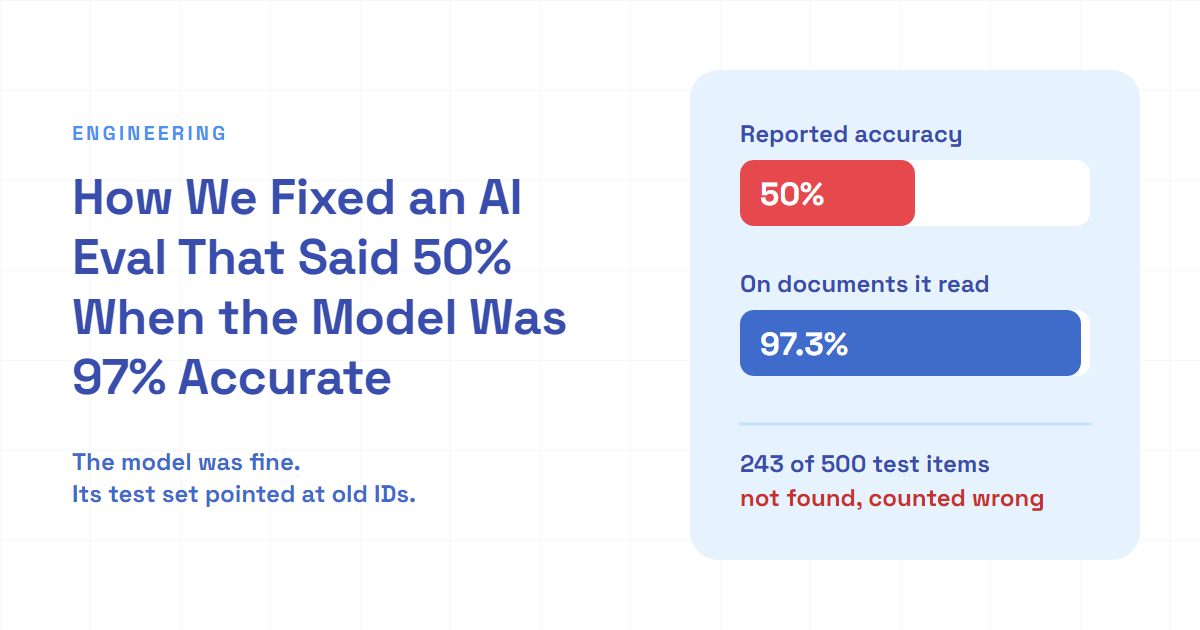
How we built an LLM classification validator: one model proposes labels with reasons, a second votes keep or drop, and a broken vote keeps every label.
Utkarsh Gupta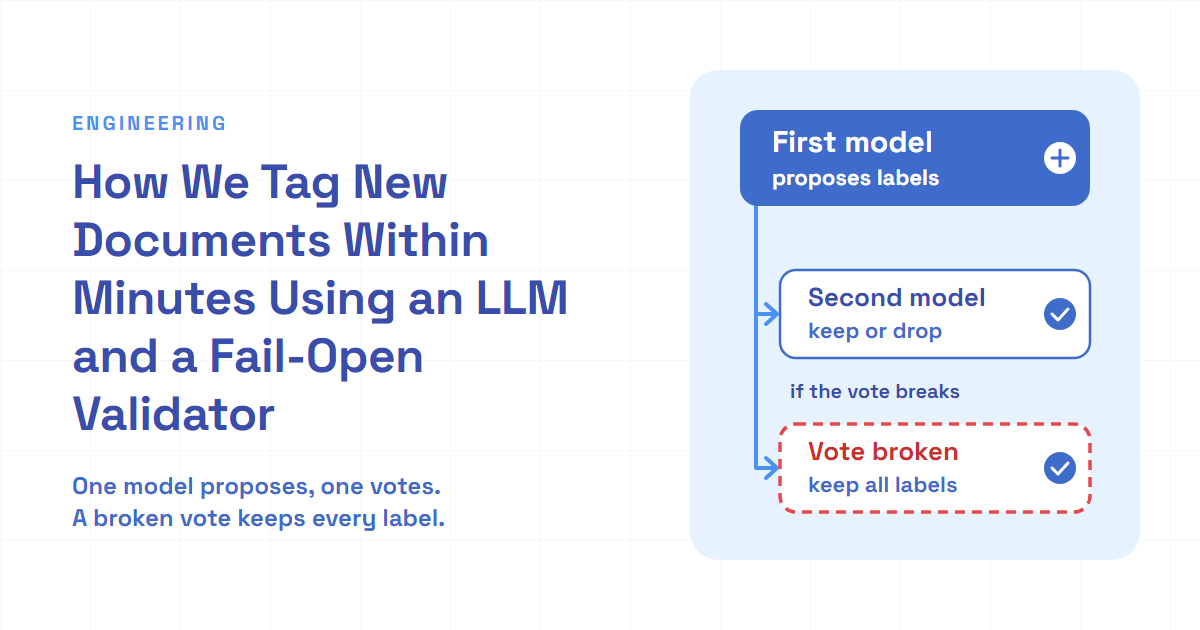
RAG retrieval evaluation with a golden set: fixing our test cut page accuracy from 67.5% to 56.1% with no change to search. Why the lower number was true.
Utkarsh Gupta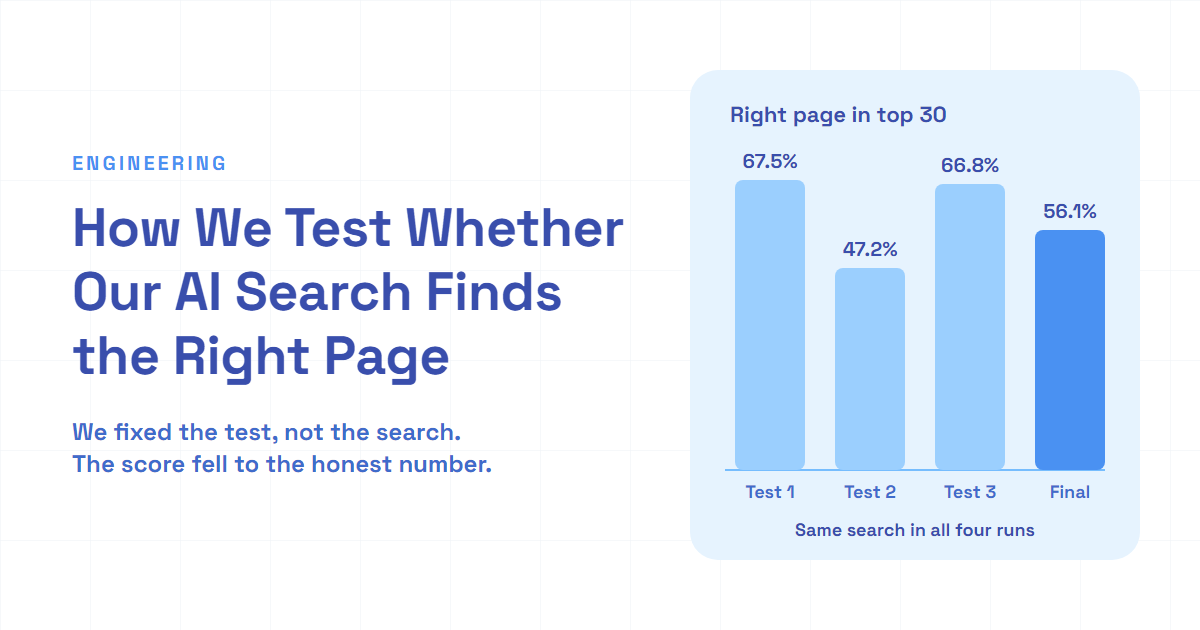
We stopped rendering PDF pages to images and sent PDFs directly to a vision LLM in 40-page parts. A week-long backfill finished in three days. Here's the cost.
Utkarsh Gupta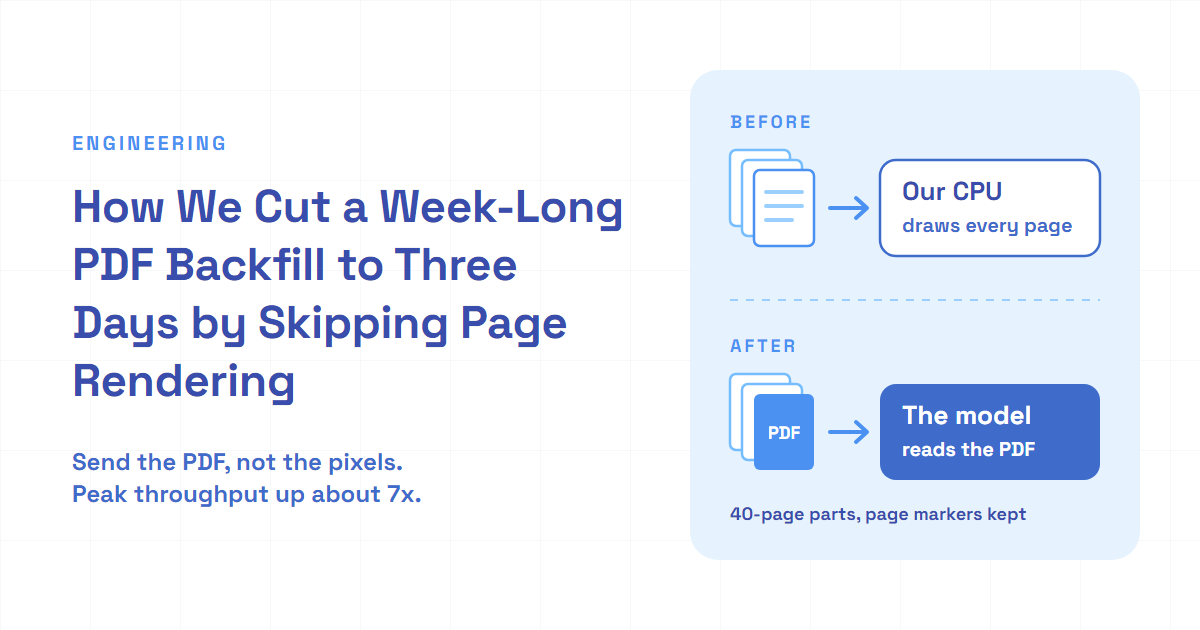
LLM article generation from long documents: how we turn a 591-page file into grounded articles, drop repeat stories by meaning and keep IDs stable across runs.
Utkarsh Gupta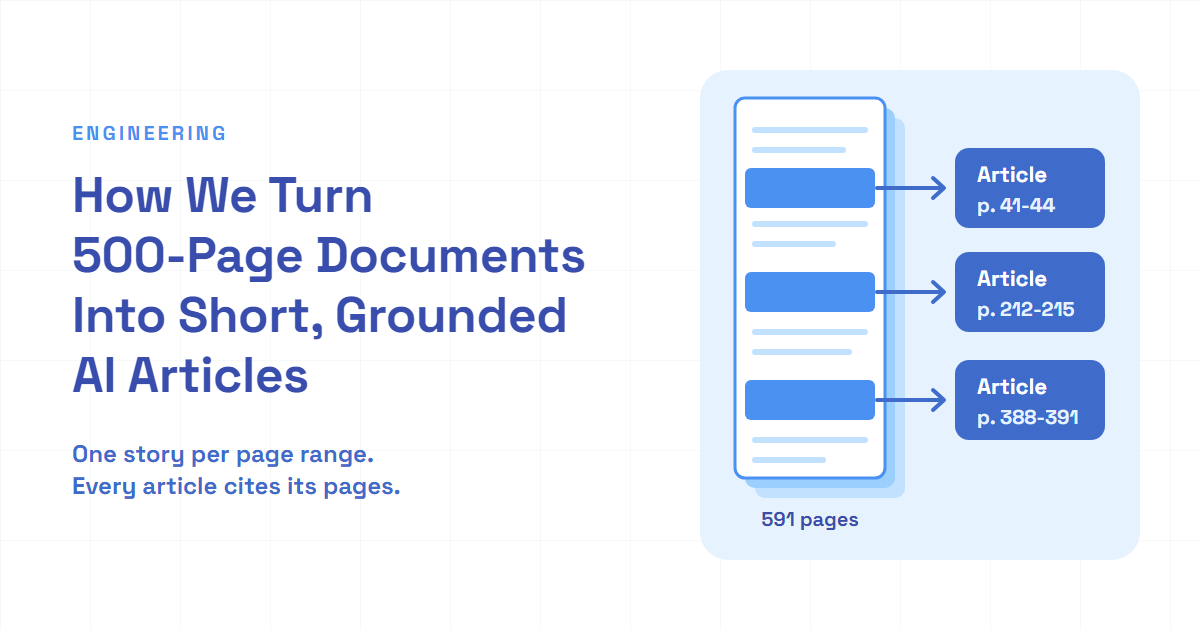
How we built an LLM document classifier: one model call returns five fields, label rules written as decision tests, our own schema check and a weekly eval.
Utkarsh Gupta