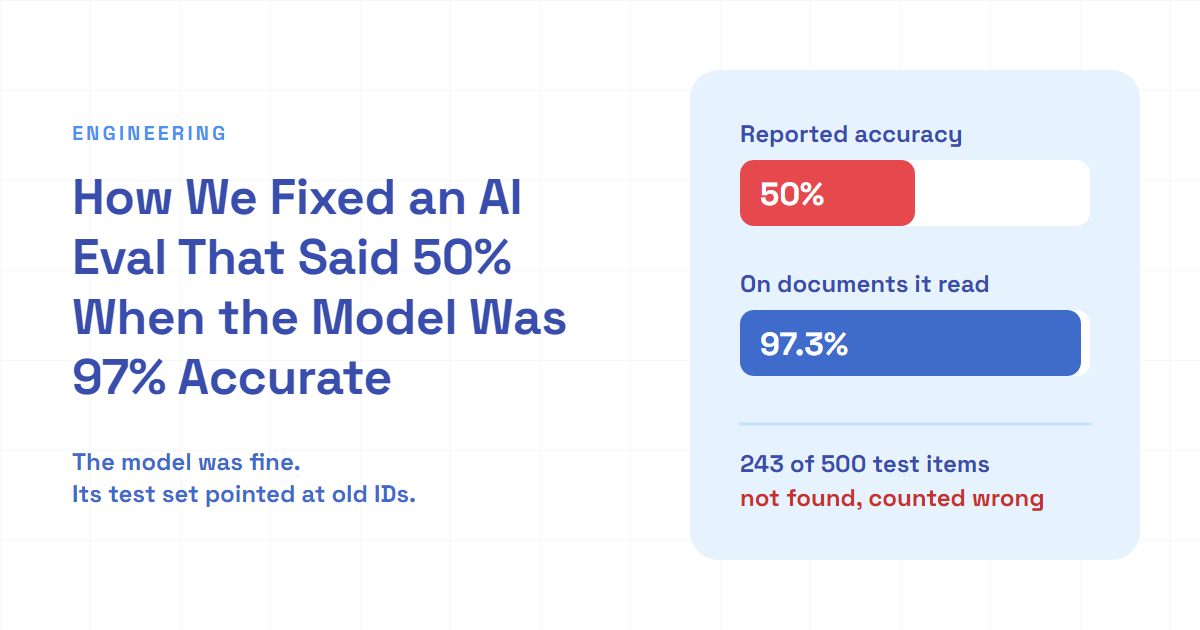
How We Fixed an AI Eval That Said 50% When the Model Was 97% Accurate
Our eval accuracy drop to 50% wasn't the model. Half the golden set pointed at retired IDs. How we remapped 1,009 items by content hash and fixed the labels.
 Utkarsh Gupta





IRIS
Multibagg AI is an AI powered stock research and analysis platform. We provide data, information, content, and analytics for publicly traded Indian companies listed on NSE and BSE. AI can make mistakes, check important information.
Prices might be delayed by a few minutes.
Join our Exclusive Community


Join our Exclusive Community
Made with 💙 in India. © Finsky Technologies Pvt Ltd. 2026


Our eval accuracy drop to 50% wasn't the model. Half the golden set pointed at retired IDs. How we remapped 1,009 items by content hash and fixed the labels.
Utkarsh GuptaHow we built an LLM document classifier: one model call returns five fields, label rules written as decision tests, our own schema check and a weekly eval.
Utkarsh Gupta